
Dispersion Explained: Measures, Examples & Uses
Dispersion measures how widely data values are spread around a central value, helping you understand variability, consistency, and data reliability. Learn the key measures of dispersion, including range, variance, standard deviation, and interquartile range, along with practical examples, real-world applications, and their importance in modern data analysis and AI-powered analytics.
A measure of dispersion tells you how spread out a set of values is. The average shows the center. Dispersion shows whether the values sit close to that center or are scattered far from it. This guide explains range, interquartile range, mean absolute deviation, variance, standard deviation, and relative measures such as the coefficient of variation.
Questions This Guide Answers
Why is variability as important as the mean or median? How do range, variance, and standard deviation differ? When is the interquartile range a better choice? How do you compare spread across data sets with different scales? These questions matter because two groups can have the same average and still behave very differently.
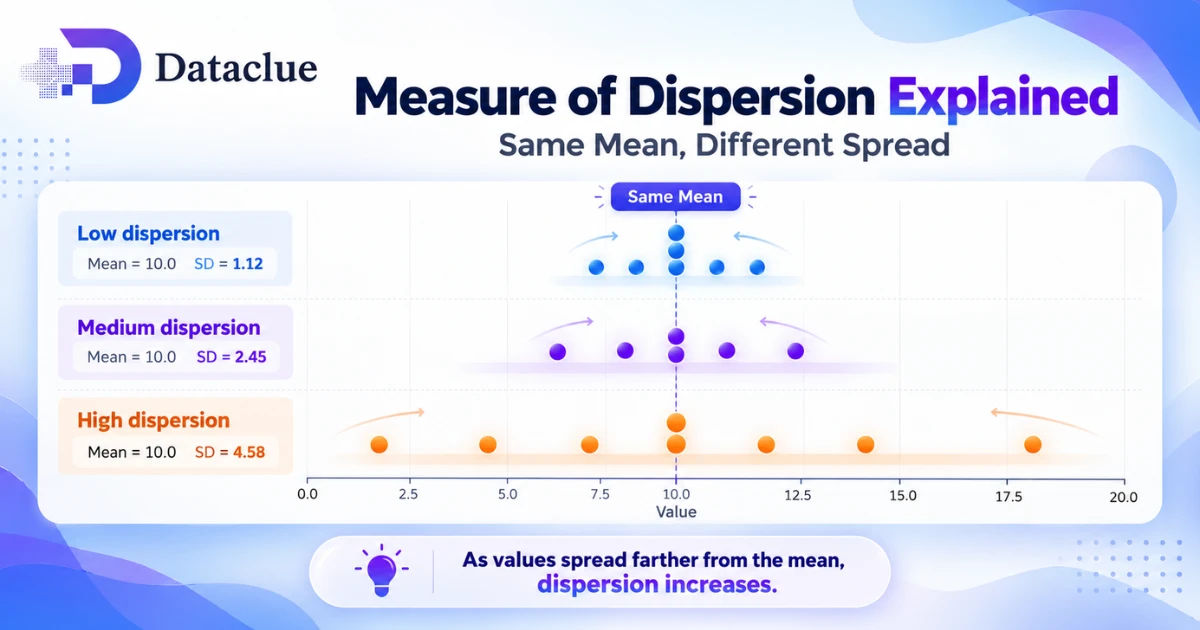
Figure 1. Both data sets have a mean of 10. Dataset B is much more spread out, so its standard deviation is much larger.
What Is a Measure of Dispersion in Statistics?
A measure of dispersion is a number that describes the spread of data. It tells you how much the values differ from one another or from a central value such as the mean or median. Low dispersion means the values are close together. High dispersion means the values are more scattered.
Imagine two classes that both have an average test score of 70. In the first class, most students score between 65 and 75. In the second class, scores range from 30 to 100. The same average tells two very different stories. A measure of dispersion reveals that difference.
Why Measures of Dispersion Matter
Looking only at the mean can hide important information. Measures of dispersion help you judge how consistent the data is, how much uncertainty exists, and whether a typical value really represents most observations.
Dispersion is useful in many settings. A teacher can compare how consistent student scores are. A business can study variation in delivery times. A researcher can see whether measurements are tightly grouped or widely scattered. An investor can study how much returns move around their average.
A complete description of numeric data often needs both a measure of center and a measure of spread. The two ideas work together.
Types of Measures of Dispersion
Measures of dispersion can be grouped into two broad types: absolute measures and relative measures.
| Type | What it tells you | Examples | Best use |
|---|---|---|---|
| Absolute measures | Show spread on the scale of the data, or in squared units for variance | Range, IQR, quartile deviation, mean absolute deviation, variance, standard deviation | Describe variability inside one data set |
| Relative measures | Show spread as a ratio or percentage | Coefficient of range, coefficient of variation, coefficient of mean deviation, coefficient of quartile deviation | Compare variability across data sets with different scales |
Absolute Measures of Dispersion
Absolute measures describe spread using the data itself. Most are expressed in the same unit as the original values. Variance is the main exception because it uses squared units.
The common absolute measures are range, interquartile range, quartile deviation, mean absolute deviation, variance, and standard deviation. Each measure answers a slightly different question, so no single measure is best in every situation.
Range
The range is the simplest measure of dispersion. It looks only at the smallest and largest values.
Range = Maximum value − Minimum value
If the lowest score is 43 and the highest score is 89, the range is 46.
The range is fast and easy to explain. Its weakness is that it ignores every value between the two ends. One extreme value can make the range much larger, even if the rest of the data is tightly grouped.
Interquartile Range and Quartile Deviation
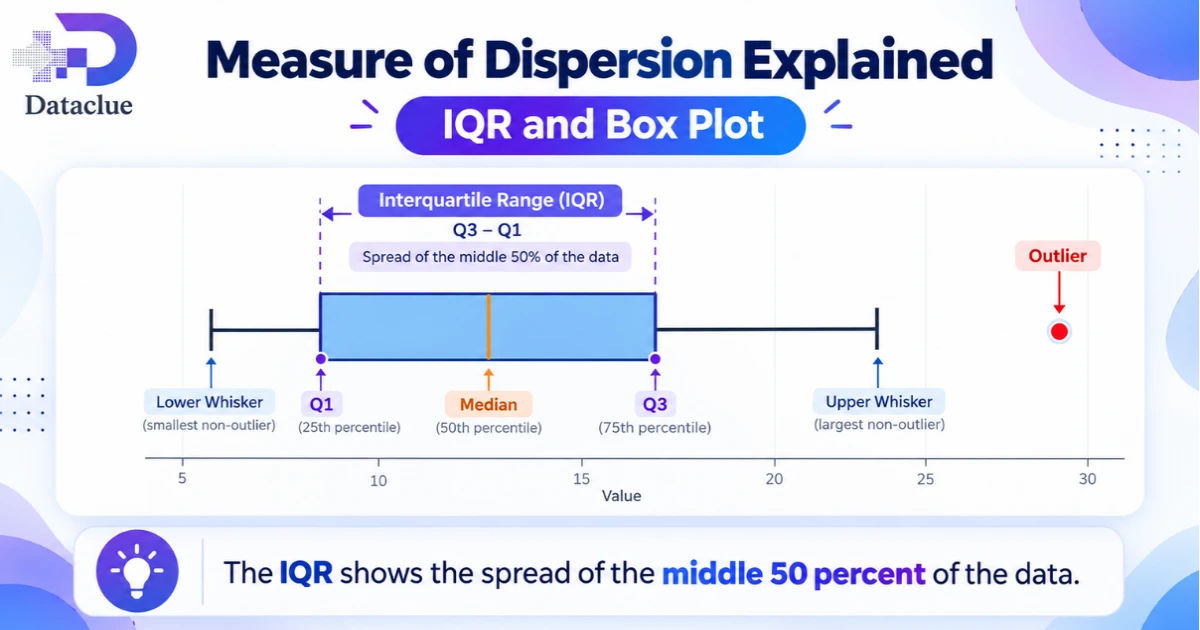
The interquartile range, often written as IQR, focuses on the middle 50 percent of the data. It uses the first quartile, Q1, and the third quartile, Q3.
IQR = Q3 − Q1
The IQR is useful when data is skewed or contains outliers because extreme values have less effect on it. This makes the IQR a strong partner for the median.
Quartile deviation is half of the IQR.
Quartile deviation = (Q3 − Q1) / 2
Mean Absolute Deviation (MAD)
Mean absolute deviation tells you the average absolute distance of values from a chosen center, usually the mean. The word absolute means that negative and positive differences are both treated as positive distances.
Mean absolute deviation = Sum of |value − mean| / number of values
Suppose the mean is 10. If one value is 7, its distance from the mean is 3. If another value is 13, its distance is also 3. MAD averages these distances for all values.
Variance
Variance measures spread around the mean by squaring each deviation from the mean and then averaging those squared deviations. Squaring prevents positive and negative differences from canceling each other.
Variance is very important in statistics because many methods are built on it. The main difficulty is interpretation. If the original data is measured in centimeters, the variance is measured in square centimeters. That is why standard deviation is often easier to explain to readers.
Population variance = Sum of (value − population mean) squared / population size
Standard Deviation
Standard deviation is the square root of variance. It gives a clear summary of how much values spread around the mean. Because the square root returns the result to the original unit, standard deviation is easier to interpret than variance.
Standard deviation = Square root of variance
A small standard deviation means values are packed more closely around the mean. A large standard deviation means values are more spread out. Standard deviation uses every observation, which makes it informative, but it can also be strongly affected by extreme values.
For fairly symmetric continuous data without major outliers, the mean and standard deviation are a common pair. For strongly skewed data or data with outliers, the median and IQR are often easier to trust.
Population Variance and Population Standard Deviation
Use population variance and population standard deviation when your data contains the full population you want to describe. If you record the final test score for every student in one class and that class is the full group of interest, you can treat it as a population for that question.
Population variance: divide the sum of squared deviations by N Population standard deviation: take the square root of the population variance
Here, N is the number of values in the population.
Sample Variance and Sample Standard Deviation
Use sample variance and sample standard deviation when you have only part of a larger population and want the sample to estimate population variability.
Sample variance: divide the sum of squared deviations by n − 1 Sample standard deviation: take the square root of the sample variance
The use of n minus 1 helps correct the tendency of a sample to underestimate population variance. For beginners, the key point is simple: use the sample formula when your data is a sample and the population formula when you truly have the full population for the question being asked.
Relative Measures of Dispersion
Relative measures are useful when you want to compare variability across data sets that have different scales. They are ratios, so they do not keep the original measurement unit.
Coefficient of Range
Coefficient of range = (Maximum − Minimum) / (Maximum + Minimum)
Coefficient of Variation
The coefficient of variation, or CV, compares standard deviation with the mean. It is usually shown as a percentage.
Coefficient of variation = (Standard deviation / Mean) × 100
A lower CV usually means greater consistency relative to the average. A higher CV means greater relative variability.
Coefficient of Mean Deviation
Coefficient of mean deviation = Mean deviation / chosen central value
Coefficient of Quartile Deviation
Coefficient of quartile deviation = (Q3 − Q1) / (Q3 + Q1)
Measures of Dispersion Formula
| Measure | Simple formula | What it focuses on |
|---|---|---|
| Range | Maximum − Minimum | Total distance from the smallest to the largest value |
| IQR | Q3 − Q1 | Spread of the middle 50 percent |
| Quartile deviation | (Q3 − Q1) / 2 | Half of the middle 50 percent spread |
| Mean absolute deviation | Average of absolute deviations from the center | Average distance from a chosen center |
| Population variance | Average squared deviation from the population mean | Squared spread around the mean |
| Sample variance | Sum of squared deviations divided by n − 1 | Estimated population spread from a sample |
| Standard deviation | Square root of variance | Spread around the mean in the original unit |
| Coefficient of variation | (Standard deviation / Mean) × 100 | Relative spread as a percentage of the mean |
Measures of Dispersion and Central Tendency
Measures of central tendency and measures of dispersion answer different questions. You usually need both to understand a data set well.
| Question | Central tendency | Dispersion |
|---|---|---|
| What does it describe? | The center or typical value | The spread or variability |
| Common measures | Mean, median, mode | Range, IQR, variance, standard deviation, MAD |
| Why use it? | Find a representative value | Judge consistency and how well the center represents the data |
| Example | Average score is 70 | Most scores are within a narrow band, or spread from very low to very high |
Nominal Variable Dispersion
Nominal variables are categories with no natural numeric order, such as eye color, department name, or type of device. Standard deviation and variance do not make sense for these labels.
For nominal data, use a frequency table to see how observations are distributed across categories. If almost everyone falls into one category, the distribution is concentrated. If counts are spread more evenly across categories, the data is more diverse.
Percentages make category comparisons easier when groups have different sample sizes.
Choosing the Right Measure of Dispersion
The best measure depends on the type of data, the shape of the distribution, and the purpose of your analysis.
| Situation | Useful measure | Reason |
|---|---|---|
| You need a fast summary of total spread | Range | Very simple and quick |
| Your data is skewed or has clear outliers | IQR | Focuses on the middle half of the data |
| Your data is fairly symmetric and numeric | Standard deviation | Uses every value and stays in the original unit |
| You need a mathematical measure for further analysis | Variance | Forms the base of many statistical methods |
| You want an easy average distance from the mean | Mean absolute deviation | Easy to explain and uses every value |
| You want to compare relative variability across scales | Coefficient of variation | Expresses spread as a percentage of the mean |
| Your variable is nominal | Frequencies and percentages | Numeric distance measures are not meaningful for categories |
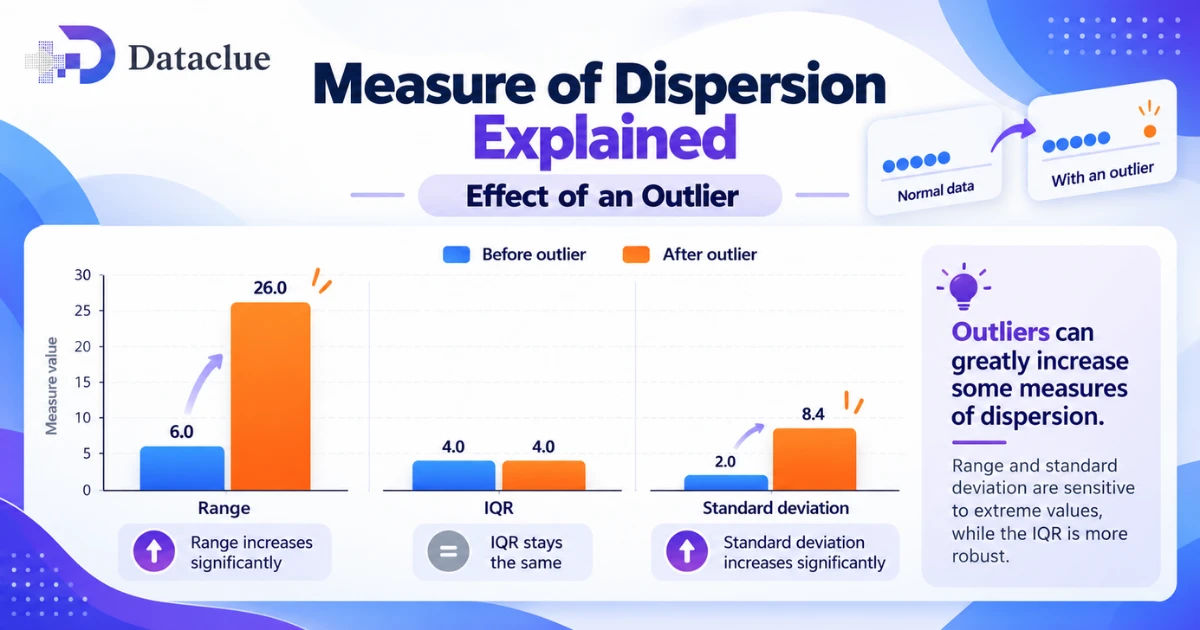 Figure 3. Range changes sharply when an extreme value is added. IQR is more resistant because it focuses on the middle part of the data.
Dispersion in Jamovi
Jamovi can calculate common measures of dispersion without requiring you to enter formulas by hand. A typical workflow is simple:
- Open the Analyses tab.
- Choose Exploration, then Descriptives.
- Move the numeric variable into the Variables box.
- Under Statistics, select standard deviation, variance, range, and IQR.
- For nominal variables, use frequency tables to inspect counts and percentages.
When you read the output, start with the sample size and missing values. Then compare the mean or median with the spread. A large standard deviation suggests wide spread around the mean. A large IQR suggests the middle half of the data is also spread out. If the range is much larger than the IQR, check for extreme values.
Software menus can change between versions, but the main ideas and statistics stay the same.
Worked Example: Calculate Measures of Dispersion Step by Step
Consider this data set:
The mean is 10. We will treat the eight values as the full population for the population calculations below.
| Value | Deviation from mean | Absolute deviation | Squared deviation |
|---|---|---|---|
| 6 | −4 | 4 | 16 |
| 8 | −2 | 2 | 4 |
| 8 | −2 | 2 | 4 |
| 9 | −1 | 1 | 1 |
| 10 | 0 | 0 | 0 |
| 11 | 1 | 1 | 1 |
| 12 | 2 | 2 | 4 |
| 16 | 6 | 6 | 36 |
| Total | 0 | 18 | 66 |
Range
16 minus 6 gives a range of 10.
Interquartile range
Using the simple method that splits the ordered data into equal lower and upper halves, Q1 is 8 and Q3 is 11.5. The IQR is 3.5. Quartile methods can vary slightly across software, so state the method when exact quartile values matter.
Mean absolute deviation
The absolute deviations total 18. Divide 18 by 8. The MAD is 2.25.
Population variance
The squared deviations total 66. Divide 66 by 8. The population variance is 8.25.
Population standard deviation
The square root of 8.25 is about 2.87.
Sample variance and sample standard deviation
If the same eight values were treated as a sample from a larger population, divide 66 by 7. The sample variance is about 9.43, and the sample standard deviation is about 3.07.
Coefficient of variation
Using the population standard deviation, 2.87 divided by 10 and multiplied by 100 gives a CV of about 28.7 percent.
Examples on Measures of Dispersion
Example 1: Same average, different spread
Dataset A is 8, 9, 10, 10, 10, 10, 11, 12. Dataset B is 2, 6, 8, 10, 10, 12, 14, 18. Both have a mean of 10, but Dataset B has much greater dispersion. This is why an average alone is not enough.
Example 2: One extreme value
Compare 4, 5, 6, 7, 8, 9, 10 with 4, 5, 6, 7, 8, 9, 30. The second set has one very large value. The range and standard deviation rise sharply. The IQR changes much less. This shows why IQR is useful when outliers are present.
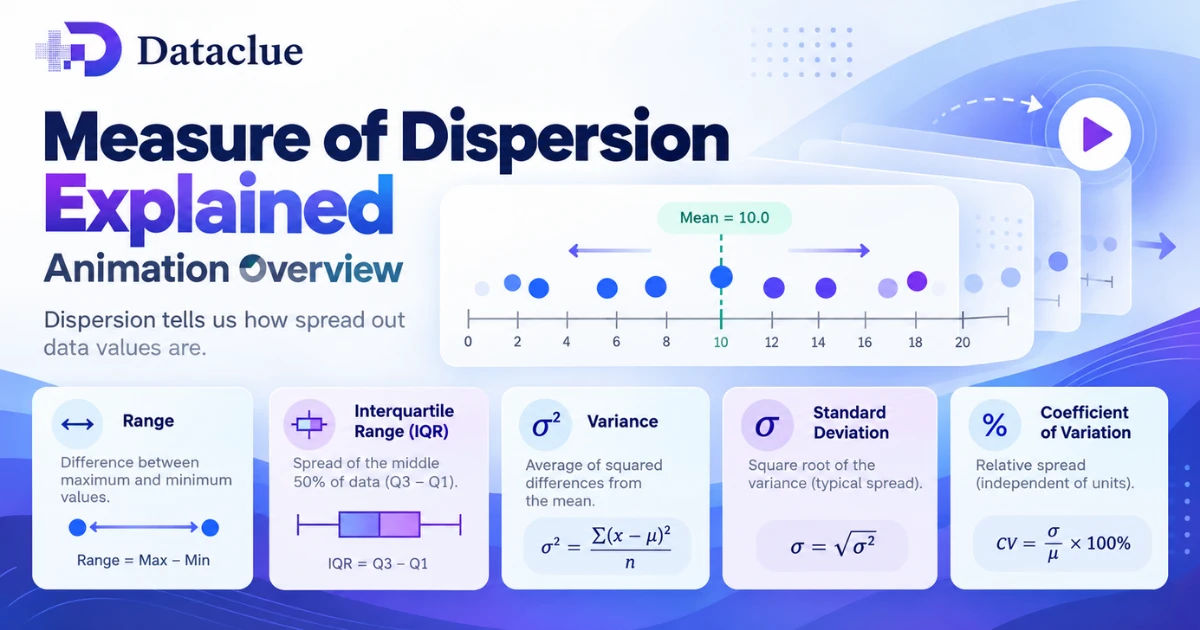 Figure 4. Animation preview. For web publishing, use the companion animated WebP. The points move outward while the mean stays at 10, so the standard deviation rises.
Common Mistakes When Interpreting Dispersion
- Looking only at the mean. Two data sets can have the same mean and very different spread.
- Using the range as the only measure. Range depends on just two values and can be distorted by an outlier.
- Using standard deviation for strongly skewed data without checking the shape. IQR may describe typical spread more clearly.
- Mixing population and sample formulas. Decide whether you have the whole population or a sample.
- Forgetting the units. Standard deviation uses the original unit. Variance uses squared units.
- Comparing standard deviations across very different scales without context. A coefficient of variation can help when a relative comparison makes sense.
- Using CV when the mean is near zero. The percentage can become unstable.
- Assuming a larger spread is always bad. The meaning depends on the question. Wider variation can signal risk, diversity, flexibility, or real differences.
Real World Uses of Measures of Dispersion
Education: Standard deviation can show whether exam scores are consistent or widely different even when the class average is unchanged.
Business: A company can compare variation in delivery times, product weights, waiting times, or monthly sales.
Finance: Analysts use measures of variability to study how much returns move around an average. The exact measure chosen depends on the goal and assumptions.
Health research: Researchers often report spread together with a center so readers can see how variable measurements are across participants.
Quality control: Low spread can show a process is consistent. A sudden rise in spread can be a warning that something changed.
Frequently Asked Questions About Measures of Dispersion
What are the main measures of dispersion?
The most common measures are range, interquartile range, mean absolute deviation, variance, and standard deviation. Relative measures include the coefficient of variation and other coefficients of dispersion.
Why do we calculate measures of dispersion?
They show how much values vary. This helps us understand whether an average is representative, whether a process is consistent, and how much uncertainty or diversity exists in the data.
What is the difference between absolute and relative measures of dispersion?
Absolute measures describe spread on the scale of the data or in squared units. Relative measures use ratios or percentages, which makes some comparisons across scales easier.
Which measure of dispersion should I use?
Use standard deviation for fairly symmetric numeric data when the mean is useful. Use IQR for skewed data or data with outliers. Use range for a quick total spread. Use CV when you need a relative comparison and the mean is meaningful and not close to zero.
Is variance the same as standard deviation?
No. Variance is the average squared spread around the mean. Standard deviation is the square root of variance and returns the result to the original measurement unit.
Why is IQR resistant to outliers?
IQR uses Q1 and Q3, so it focuses on the middle 50 percent of the ordered data. Very small or very large values at the ends usually have less effect on it.
Can dispersion be zero?
Yes. If every value in a numeric data set is exactly the same, there is no spread. The range, variance, standard deviation, IQR, and mean absolute deviation can all be zero in that special case.
Key Takeaways
- Dispersion describes how spread out data is.
- Range is simple but highly sensitive to extreme values.
- IQR describes the middle 50 percent and is useful for skewed data or outliers.
- Mean absolute deviation gives an easy average distance from a center.
- Variance uses squared deviations and is important for many statistical methods.
- Standard deviation is the square root of variance and uses the original data unit.
- Sample variance uses n minus 1 in the denominator.
- Coefficient of variation compares standard deviation with the mean and is useful for some relative comparisons.
- For nominal variables, use counts and percentages rather than numeric distance measures.
- A strong data summary usually combines a measure of center with a suitable measure of spread.
Sources and Further Reading
This article uses original explanations and examples while drawing on the topic coverage in the following educational references:
Try it in DataClue
Ready to run Summary Statistics?
Calculate mean, median, mode, standard deviation, variance, range, and quartiles for your data.
Run Summary Statistics